Apple Intelligence and On-Device AI: Opportunities and Limitations for RAG
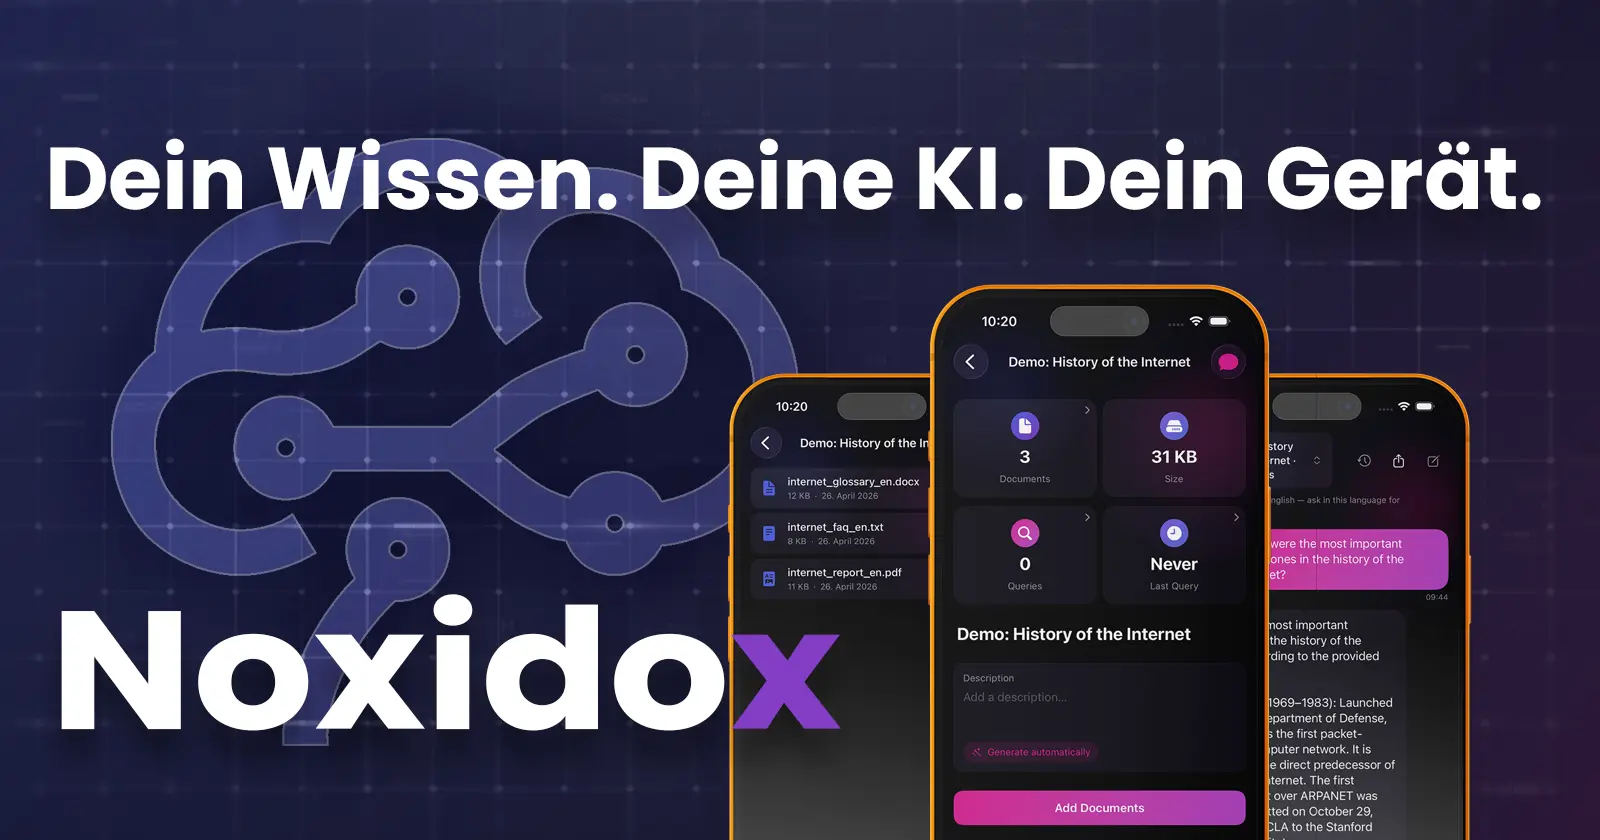
What is Apple Intelligence and what does it entail? It is a concept that brings generative AI directly to the iPhone, iPad, and Mac. A key component of this is the ability to run AI models directly on the device. This offers advantages in terms of data privacy, speed, and integration, but it also presents unique challenges for applications like the Noxidox app.
I found the combination of on-device AI and Retrieval-Augmented Generation (RAG) particularly interesting when it comes to processing personal documents. This is because the documents can be processed locally while a language model accesses the information relevant to a query.
However, local execution has its limits—particularly regarding the available context window of the on-device LLM.
What is Apple Intelligence?
Apple Intelligence is Apple’s platform for generative and context-aware AI capabilities. It connects various AI models and system features and is deeply integrated into Apple’s operating systems.
This includes the Foundation Models. These are language models (LLMs) that can run directly on compatible devices as well as utilize cloud computing. This allows certain AI tasks to be processed locally on the iPhone, iPad, or Mac without having to transfer the necessary data to an external AI provider. This is particularly important for personal and sensitive information.
If the device’s computing power is insufficient for a task, Apple also employs the Private Cloud Compute (PCC) approach. More complex calculations can be performed on servers specifically designated for this purpose, provided the developer has integrated this option.
In doing so, Apple is pursuing an approach that integrates data privacy and local processing as closely as possible with modern generative AI.
That’s exactly why I chose this approach for my Noxidox app: to process documents locally and make them searchable using RAG technology, while the AI also runs directly on the device.
What advantages does Apple Intelligence offer over open-source models?
Open-source AI models offer us developers a great deal of freedom. They can also be run on our own hardware. Furthermore, they can be customized and optimized for specific use cases. Apple Intelligence, on the other hand, takes a more integrated approach. This results in several unique advantages, particularly on Apple devices.
Optimization for Apple Silicon
Apple controls both the hardware and a large portion of the software platform. The foundation models can therefore be specifically optimized for the characteristics of Apple Silicon CPUs and the integrated Neural Engine. This enables efficient execution of the on-device AI model on the devices.
While any open-source model can also be run locally, it is not necessarily optimized for the specific hardware.
Deep Integration into iOS and macOS
Apple Intelligence is not an isolated AI service. It is an integral part of the Apple ecosystem. Apple provides frameworks to integrate this functionality into developers’ own apps, opening up possibilities for system-wide AI features.
Energy-Efficient On-Device AI
AI models typically require significant computing power. On a mobile device, therefore, not only speed but also energy consumption is critical. Optimizing models and hardware for Apple devices makes it possible to run AI tasks on-device without necessarily requiring the resources of a large cloud server.
The Challenge of On-Device Processing: The Context Window
A language model cannot process an unlimited amount of information at once. The amount of text a model can consider in a single query is limited by its context window. In Apple’s on-device models, this context window is relatively small. For standard AI tasks, this is often not a major issue. However, when processing large collections of documents, this limitation becomes particularly significant.
Why Is This Important for RAG?
The basic principle is simple:
- A question is asked.
- The system searches the available documents for relevant information.
- The text passages found are passed to the language model as context.
- The model uses this to generate a response.
The language model therefore does not need to know all the documents. It only receives the information relevant to the current question. This is precisely where a small context window poses a challenge.
Not all relevant information fits into the context
Let’s imagine a collection of documents containing several hundred PDFs. For example, a user might ask: “What changes were made between the contracts from 2023 and 2025?”
The RAG system must first identify the relevant documents and text passages.
With a very large context window, large amounts of this material could then be passed on to the language model. With a small on-device context window, this isn’t possible. The system must therefore decide much more precisely which information is actually passed on to the language model. This shifts part of the task from the LLM to the retrieval layer.
Why Good Retrieval Is Especially Important in On-Device AI
In a RAG system with a limited context window, it’s not enough to simply pass as many search results as possible to the language model. The relevant information must be identified and prioritized as precisely as possible. To achieve this, I’ve combined different search methods at Noxidox.
For example, a semantic search finds text passages whose content matches a question, even if the terms used are different.
A classic full-text search, on the other hand, is particularly reliable at finding specific terms.
At Noxidox, combining both methods helps filter out exactly the information needed for the current query from a large collection of documents. The result is then reduced to a compact context that the on-device LLM can actually process. In simplified terms, the architecture looks like this:
Documents → Search → Relevance Assessment → Context Processing → On-Device LLM → Response
So the language model doesn’t need to receive as much information as possible. It needs to receive the right information.
Conclusion: On-Device AI Requires Intelligent Retrieval
Apple Intelligence demonstrates that modern generative AI can increasingly run directly on our devices. This is particularly interesting for applications involving sensitive information, because data can be processed locally and does not necessarily have to be transferred to external AI services.
At the same time, on-device AI operates under different constraints than large cloud-based models. The comparatively small context window of Apple’s models poses a particular challenge for RAG applications.
The solution isn’t necessarily to use a larger model. Instead, the quality of retrieval becomes crucial.
This is because a RAG system does not need to pass all knowledge to the language model. It must ensure that exactly the right information reaches the model at the right moment within the context of the model.
This is one of the most exciting features of on-device AI: A system’s intelligence does not arise solely from the language model, but from the interplay of documents, retrieval, context, and the AI model.
For Noxidox, this means that the strength of on-device AI does not lie in passing as much data as possible to a model. It lies in finding relevant information locally and making it available to the AI model efficiently.
Comments
No comments yet. Be the first to write one!